Menu

Posts tagged “engineering”

Building Engineering

This is a really great post by Ben Werdmuller. On the surface it’s about Building Engineering, but it’s mostly about good leadership and how to build successful products. I very much agree with his conclusion:

The most interesting and successful organizations have an externally-focused human mission and an internal focus on treating their humans well. That’s the only way to build technology well: to empower the people who are doing it, with a focus on empathy and inclusion, and a mission that galvanizes its community to work together.

There’s some great advice throughout, so I recommend reading the whole thing!
Evolving our organization: introducing Engineering Managers and Engineering Leads

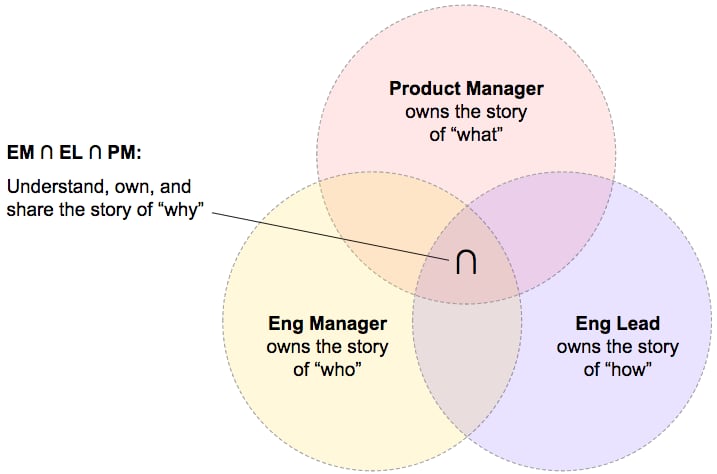
I’ve been digging into different ways to structure engineering teams a bit, and I like this take on the different roles of Engineering Managers and Engineering Leads:

It became obvious that in most cases it’s too much for one person to manage people (growth, performance and motivation), along with driving technical execution. At the same time, in most teams, we had one or more senior developers on whom Tech Lead could rely and delegate architecture decisions, quality, mentorship, etc… We decided to give these engineers roles to make them recognized in the company for their impact, also to improve communication channels, and to help team and product leads. We introduced the role of Engineering Lead to have a major influence on how we build products. Additionally, we replaced the Tech Lead role with the Engineering Manager role, which gave more focus on people and team management (“who”).

It also reminded me of Lara Hogan’s excellent post on how Engineering Managers and Engineering Leads work with Product:

What if everybody did everything right?

Here’s Lorin Hochstein with another great post about the practice of learning from software incidents. He asks, What if everybody did everything right?

An alternative lens for making sense of an incident is to ask the question “how did this incident happen, assuming that everybody did everything right?” In other words, assume that everybody whose actions contributed to the incident made the best possible decision based on the information they had, and the constraints and incentives that were imposed upon them.

Removing React is just weakness leaving your codebase

I’ve been seeing a lot of this type of sentiment about React recently…

By my reckoning, if you’ve maintained a React codebase for the past decade, you’ve re-written your application at least three times and possibly four. […]

By choosing React, we’ve signed up for a lot of unplanned work. Think of the value we could have produced for our users and company if we weren’t subject to the whims of whatever the cool kids were doing over in React.

My $500M Mars Rover Mistake: A Failure Story

My work at Jeli so far has given me a new lens on “incidents”—both in the software world and beyond—that I didn’t have before. These “failures” are everywhere around us. But are they really failures? Or are they ways for us to learn more about the systems we work within, and how to improve them? I think it’s the latter, and My $500M Mars Rover Mistake by Chris Lewicki is another story that showcases that…

The core lesson I’ve drawn from my rover ordeal is best expressed in these words: Let your scars serve you; they are an invaluable learning experience and investment in your capability and resilience.

2023 State of DevOps Report: Culture is everything

There’s some good insights in this year’s 2023 State of DevOps Report. It’s well worth skimming through. Things like this aren’t exactly surprising, but it’s nice to have some data around it:

Teams with generative cultures, composed of people who felt included and like they belonged on their team, have 30% higher organizational performance than organizations without a generative culture.

Error budgets and the legacy of Herbert Heinrich

This is an older post from Lorin Hochstein but it’s new to me, and really insightful. It’s about how to best use our knowledge about the past behavior of a software system to figure out where we should invest our time to improve the system—and how the common method of error budgets is generally not a good way to do this:

I’m skeptical about relying on predefined metrics, such as reliability, for getting insight into the risks of the system that could lead to big incidents. Instead, I prefer to focus on signals, which are not predefined metrics but rather some kind of information that has caught your attention that suggests that there’s some aspect of your system that you should dig into a little more.

So basically, vibe-based incident analysis is where it’s at.

How GitHub Engineering communicates

This is a great document outlining the communication principles followed by GitHub Engineering. I’d say this is broadly applicable to teams and organizations—not just Engineering. I love this point about making work visible:

Capturing and exposing processes through URLs also helps make your work more visible. So work in the open and proactively share your work to the widest extent practical. As we continue to grow as an organization, points of collaboration will become even more important as we try to reduce redundant work. Avoid hoarding information: Like in any production system, observability is key. And if you make something useful, find a way to make it available so others can benefit from it too.

“Healthy tension” between Product and Engineering? No thanks, I’d prefer alignment.

I’ve always been adamant that Product and Engineering are in a partnership, not a “healthy tension” relationship. So I very much agree with this post:

The problem is in the assumption that Product and Engineering teams inherently have different goals. They don’t. Both teams are responsible for the growth and stability of the company, for revenue and scalability. Neither can succeed without the other. When we assume otherwise, we sell each side short.

Incidents can't be prevented, but learned from

Here’s a good reminder that Incidents can’t be prevented, but learned from:

But approaching incidents with a mindset of learning makes it an exciting rather than painful situation. Because you’ll know you’ll never run out of sources for learning. And once you’ve realised what a good source for learning incidents are, it’s maybe even time to take a good look whether shallow incident data like “mean time to detection” and “mean time to resolution” (or the maybe worst offender of all “mean time between failure”) are actually helping your team approach incidents as a learning opportunity or maybe are incentivising an approach that foregoes learning for a better look of those metrics.